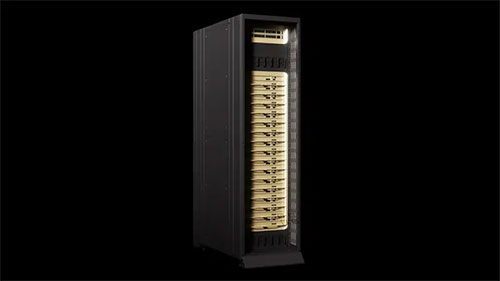
At the Hot Chips 2026 conference on August 24 local time, NVIDIA announced that its Groq 3 LPX interactive AI inference‑acceleration system is now in full‑scale production. An extension of the Vera Rubin platform, a single Groq 3 LPX rack is equipped with 256 Groq 3 LPUs. Delivering ultra‑fast token generation, it substantially boosts AI‑inference performance for highly‑responsive agent systems. Nebius, an AI cloud‑service provider, has become the first‑mover to deploy Groq 3 LPX. Looking ahead, Nebius will combine the system with the next‑generation Vera Rubin NVL72 and roll it out on its Token Factory inference platform.
As AI applications gradually shift from model training to inference, the arrival of the Agent AI era has triggered explosive growth in inference demand.
According to NVIDIA, the inference workflow can be broadly split into two phases: Context and Generation. The Context phase reads long prompts, large‑scale code and continuously‑accumulated agent states generated during multi‑turn interactions. After processing this input, the Generation phase incrementally produces tokens that end‑users or AI agents can view and act upon.
Since an AI agent may need to call a model dozens of times consecutively to finish one task, repeatedly process massive volumes of context and historical task data, and execute each step conditional on results from the previous step, latency accumulates throughout the workflow. Faster token generation is therefore critical for real‑time inference, action execution and complex‑task completion by AI agents.
Groq 3 LPX is purpose‑built to meet requirements for long‑context processing and low‑latency inference. A single LPX rack houses 256 LPU accelerators, 128 GB of on‑chip SRAM and delivers 640 TB/s of scale‑up bandwidth. Built on NVIDIA’s MGX rack architecture with an all‑liquid‑cooled design, it leverages the LPU architecture to accelerate token generation for AI inference.
Benchmark tests carried out by third‑party AI evaluator Artificial Analysis show that, when running the Gemma 4 31B model under a 100K‑token context window, Groq 3 LPX achieves a median output speed of 3,431 tokens per second; the figure reaches 3,382 tokens per second under a 10K‑token context window. This marks an all‑time‑high performance record for the model. Using workloads developed via NVIDIA’s SPEED‑Bench test suite, Groq 3 LPX further delivers a median token‑output throughput of 4,767 tokens per second and a P80 throughput of 5,520 tokens per second.
NVIDIA states that Groq 3 LPX cuts the runtime of agent‑oriented tasks such as coding from hours down to minutes. It delivers four‑times‑faster response speeds for agents and latency‑sensitive workloads compared with its closest competing platform.
Notably, Groq 3 LPX is not intended to replace Vera Rubin NVL72. Instead, the two hardware solutions divide AI‑inference workloads more efficiently.
NVIDIA indicates that Groq 3 LPX is designed to expand the interactive capability of Vera Rubin — namely the token‑generation speed for individual users, which determines how rapidly an AI agent completes every step of its workflow. Higher‑speed token generation grants agents extra time to inspect documents, write and test code, invoke tools, validate outcomes and iterate, while maintaining a snappy user‑response experience.
Specifically, the two systems adopt a separated Prefill‑and‑Decode architecture. Vera Rubin NVL72 handles the Prefill stage, processes front‑end context and builds the KV Cache, after which Groq 3 LPX takes over subsequent Decode operations. Alternative configurations including Attention‑FFN separation and Speculative Decoding are also supported to allocate computing resources according to different workload characteristics.
“Inference is AI’s growth engine. NVIDIA Grace Blackwell and NVL72 have revolutionized large‑language‑model inference with unprecedented leaps in performance and efficiency,” said Jensen Huang, Founder and CEO of NVIDIA. “Vera Rubin extends this vision with workload‑optimized AI‑factory configurations built for the Agent‑AI era. Groq 3 LPX pushes the performance frontier for ultra‑fast token generation. This transforms how intelligence is produced and delivers another massive leap in AI throughput, efficiency and responsiveness amid globally accelerating demand for AI compute.”
Leading AI‑cloud provider Nebius plans to deploy NVIDIA Groq 3 LPX on its production‑grade inference platform, Nebius Token Factory, enabling developers to access ultra‑fast token generation for highly‑responsive agent‑AI applications.
“Generation is the inference phase that determines an AI system’s real‑world responsiveness — and that is exactly what NVIDIA Groq 3 LPX accelerates,” commented Danila Shtan, CTO of Nebius. “As the first AI cloud to bring this technology into production via Nebius Token Factory, we ensure every step of the agent loop feels instantaneous — through the very same APIs developers already use, with no requirement to migrate to a new tech stack.”
(Reprinted from https://news.eccn.com/)